预约演示
更新于:2026-09-20
Peking University
更新于:2026-09-20
概览
标签
肿瘤
免疫系统疾病
其他疾病
小分子化药
蛋白水解靶向嵌合体(PROTAC)
诊断用放射药物
疾病领域得分
一眼洞穿机构专注的疾病领域

技术平台
公司药物应用最多的技术
靶点
公司最常开发的靶点
关联
靶点 |
作用机制 |
在研机构 |
原研机构 |
在研适应症 |
非在研适应症 |
最高研发阶段 |
首次获批国家/地区 |
首次获批日期 |


靶点 |
作用机制 |
在研机构 |
原研机构 |
在研适应症 |
非在研适应症 |
最高研发阶段 |
首次获批国家/地区 |
首次获批日期 |
靶点 |
作用机制 |
在研机构 |
原研机构 |
在研适应症 |
非在研适应症 |
最高研发阶段 |
首次获批国家/地区 |
首次获批日期 |
NCT07822867
Effects of an Exercise Snacking Intervention on Cognitive Function in Patients With Mild Cognitive Impairment: A Nationwide Multicenter Randomized Controlled Trial
NCT07823114
Ecological Momentary Intervention for Reducing Psychological Distress in Young Adults With Multiple Adverse Childhood Experiences: A Feasibility Study
NCT07809737
The Dynamic Mechanism of Mindfulness Intervention for Emotional Distress (MIED) Based on Ecological Moment Measurement
100 项与 北京大学 相关的临床结果
登录后查看更多信息
登录后查看更多信息
2027-01-01NEURAL NETWORKS
C2LNet: Fusing infrared and visible image via a cross-modality complementarity learning network
Article
作者: Hu, Nan ; Liu, Xiaobin ; Li, Jianing ; Yuan, Jing ; Sun, Xingyu ; Wang, Pingyu
Mining and fusing complementary information across modalities are crucial for infrared and visible image fusion (IVIF), yet existing methods largely rely on implicit feature aggregation and fail to explicitly mine and preserve cross-modality complementarity. To handle this issue, this paper proposes a Cross-modality Complementarity Learning Network (C2LNet) that simultaneously mines complementary features from different modalities and ensures the embedding of those mined cues in fused images. Specifically, C2LNet uses an Interactive Complementarity Mining (ICM) method to guide the network to mine and extract complementary features from infrared and visible images with respect to different feature levels and spatial regions, providing more diverse and informative features for IVIF. To encourage fused images to contain visual features from different modalities and to be more discriminative for downstream semantic tasks, a Complementarity Fusing Constraint (CFC) is designed to supervise the training of C2LNet. CFC ensures similar embeddings of fused images and input images, and additionally enhances the discrimination capacity of fused images, thus is more effective in supervising the fusion of those complementary features mined by ICM. Extensive experiments on three widely-used datasets demonstrate that our method outperforms state-of-the-art methods by clear margins, e.g., improving VIF metric by 3.2% on RoadScene, 6.0% on M3FD, and 4.6% on LLVIP, respectively. Further experiments in an electricity factory show that C2LNet also generalizes to real-world industrial scenarios, showing potential to benefit engineering applications such as autonomous robotic inspection. Our code is available at https://github.com/XingyuNKU/C2LNet.
2027-01-01JOURNAL OF ETHNOPHARMACOLOGY
Jianpi Bushen Qingchang Huashi formula alleviates DSS-induced colitis through butyrate-associated HDAC1 inhibition and Th17/Treg homeostasis
Article
作者: Feng, Wan ; Li, Bin ; Jing, Xiaolong ; Xu, Senlei ; Ge, Lilin ; Chen, Jing ; Shen, Hong ; Lu, Yitong ; Wang, Yuhua ; Jin, Zixiang ; Cheng, Cheng ; Dai, Sining
ETHNOPHARMACOLOGICAL RELEVANCE:
Jianpi Bushen Qingchang Huashi Formula (JBQHF) is a traditional Chinese medicine compound of nine herbal ingredients clinically used to treat chronic diarrhea and dysentery syndromes, corresponding to ulcerative colitis (UC). Although clinical evidence supports its efficacy, the underlying mechanism remains unclear.
AIM OF THE STUDY:
This study sought to define the therapeutic benefit of JBQHF in a murine colitis model and to dissect the underlying mode of action.
MATERIALS AND METHODS:
Ultra-high performance liquid chromatography coupled with quadrupole time-of-flight mass spectrometry (UHPLC-QTOF-MS) was applied to profile the chemical constituents of JBQHF. Therapeutic efficacy was evaluated in a DSS-induced murine colitis model. Gut bacterial composition and metabolite output were analyzed by 16S rRNA gene sequencing and Gas chromatography-mass spectrometry (GC-MS), respectively. Network pharmacology, deep learning-based virtual screening, and molecular docking were employed to predict candidate active compounds and their potential targets. Immunological assays focused on Histone deacetylase 1 (HDAC1) expression, HDAC enzymatic activity, histone acetylation status and the T helper 17/regulatory T (Th17/Treg) differentiation axis.
RESULTS:
JBQHF attenuated colitis as reflected by lower disease activity indices (DAI) and reduced histopathologic injury. Pro-inflammatory mediators were decreased while intestinal tight junction protein levels were elevated. JBQHF was associated with increased gut microbiota-derived butyrate production, reduced colonic HDAC1 expression and HDAC enzymatic activity, elevated Acetyl-H3K9 and Acetyl-H3K27, and a rebalancing of the Th17/Treg ratio. The protective effects of JBQHF were largely abrogated by the HDAC activator ITSA-1. Deep learning-based virtual screening further identified flavonoids within JBQHF as candidate HDAC1 ligands with predicted target selectivity.
CONCLUSIONS:
JBQHF ameliorates experimental colitis via a dual inhibition of HDAC1, providing an integrated mechanism for its clinical application.
2026-12-31Human Vaccines & Immunotherapeutics
Trends in clinical intervention practice for preventing mother-to-child transmission of hepatitis B virus in Guangdong Province, 2021–2023
Article
作者: Su, Mengyang ; Zhang, Sihui ; Zhang, Xiyu ; Liu, Fenghua ; Xu, Qingsong ; Cheng, Yujie ; Xie, Tiancheng ; Cui, Fuqiang ; Cai, Min ; Gao, Shuang ; Zhao, Tianshuo ; Wang, Mingting
Guangdong Province in China is endemic for hepatitis B virus (HBV) infection with a high prevalence of chronic HBV infection in pregnant women. Measures have been taken to reduce mother-to-child transmission (MTCT) of HBV. This study aims to analyze the trends in these preventive measures in hepatitis B surface antigen (HBsAg)-positive pregnant women from 2021 to 2023. Data were obtained from the case report forms of HBsAg-positive pregnant women and their newborns that were completed and reported in Guangdong Province through the Information System of the National Integrated Prevention of Mother-to-Child Transmission of HIV, syphilis and hepatitis B Programme from January 1, 2021, to December 31, 2023. The Cochran-Armitage test was employed to analyze trends in maternal hepatitis B e antigen (HBeAg) positivity rates across different age groups of pregnant women, antiviral treatment rates in the total and HBeAg-positive populations, and the coverage of timely birth dose of the hepatitis B vaccine (HepB-BD) and hepatitis B immunoglobulin (HBIG) among infants born to the total and HBeAg-positive pregnant women from 2021 to 2023. A total of 283,959 HBsAg-positive pregnant women and their newborns were included in the study. The HBeAg positivity rate among the HBsAg-positive pregnant women was 26.1%. The prevalence of HBeAg positivity among HBsAg-positive pregnant women in Guangdong Province experienced a declining trend from 2021 to 2023. Over the same period, the uptake of antiviral treatment increased in both the overall population and the HBeAg-positive subgroup, with the proportion of HBeAg-positive pregnant women receiving antiviral therapy rising from 23.8% in 2021 to 51.8% in 2023. The proportion of HBV-exposed newborns receiving both HepB-BD and HBIG within 12 hours of birth also increased steadily, with coverage exceeding 97% in 2023. This study highlights significant progress in reducing MTCT of hepatitis B in Guangdong Province from 2021 to 2023. HBeAg positivity among HBsAg-positive pregnant women declined, while both the uptake of antiviral therapy and the timely administration of HepB-BD and HBIG to HBV-exposed infants improved markedly. These findings underscore the important role of public health interventions while emphasizing the need for sustained efforts, particularly for young HBeAg-positive pregnant women.
100 项与 北京大学 相关的药物交易
登录后查看更多信息
100 项与 北京大学 相关的转化医学
登录后查看更多信息
组织架构
使用我们的机构树数据加速您的研究。
登录
或
管线布局
2026年09月21日管线快照
管线布局中药物为当前组织机构及其子机构作为药物机构进行统计,早期临床1期并入临床1期,临床1/2期并入临床2期,临床2/3期并入临床3期
药物发现
30
191
临床前
临床申请
1
9
临床1期
临床2期
1
24
其他
登录后查看更多信息
当前项目
登录后查看更多信息
药物交易
使用我们的药物交易数据加速您的研究。
登录
或
转化医学
使用我们的转化医学数据加速您的研究。
登录
或
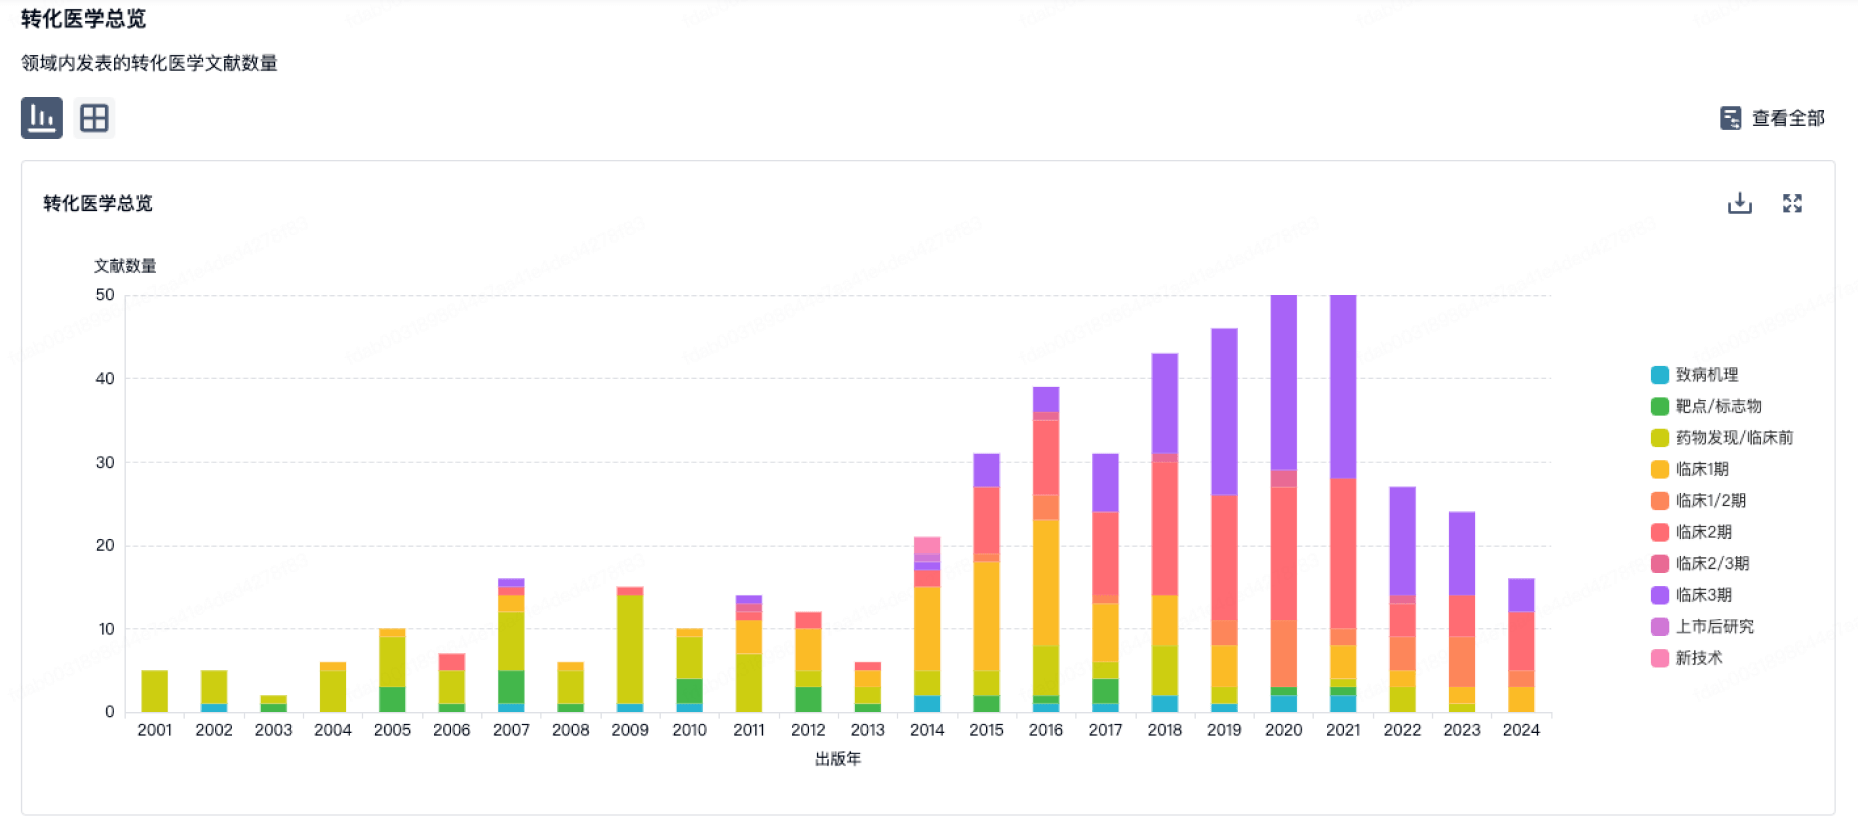
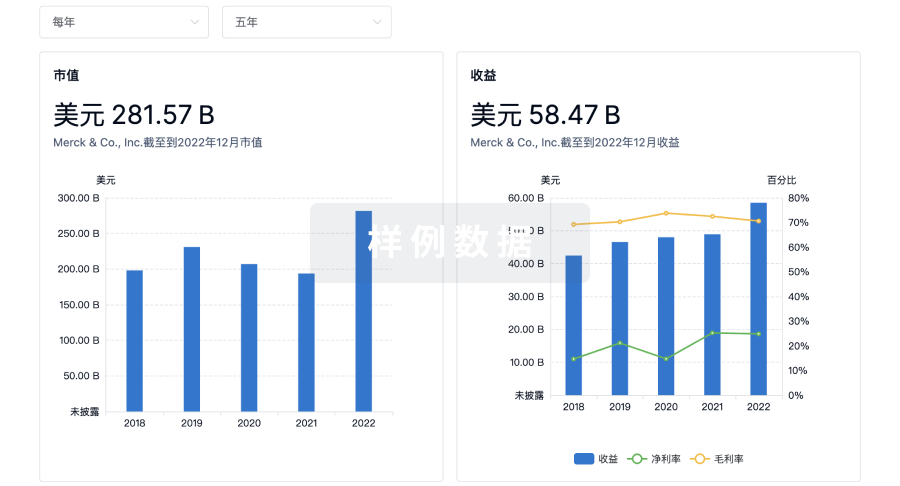
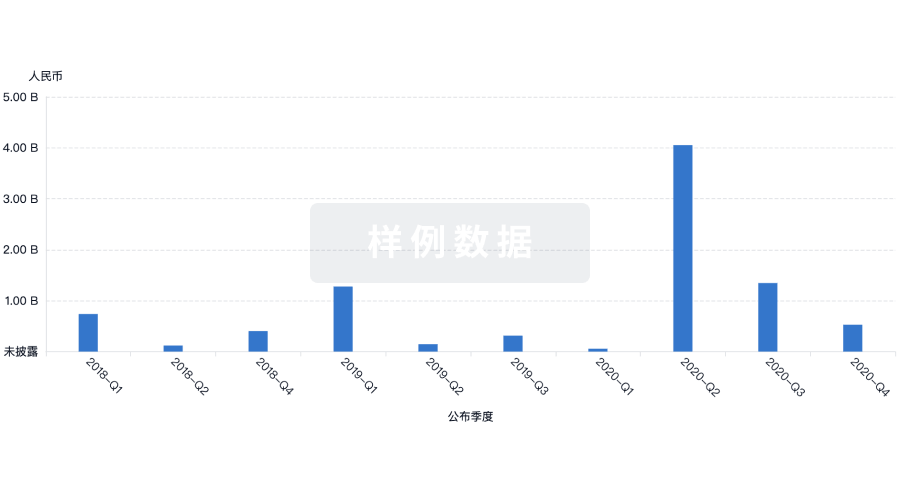
营收
使用 Synapse 探索超过 36 万个组织的财务状况。
登录
或
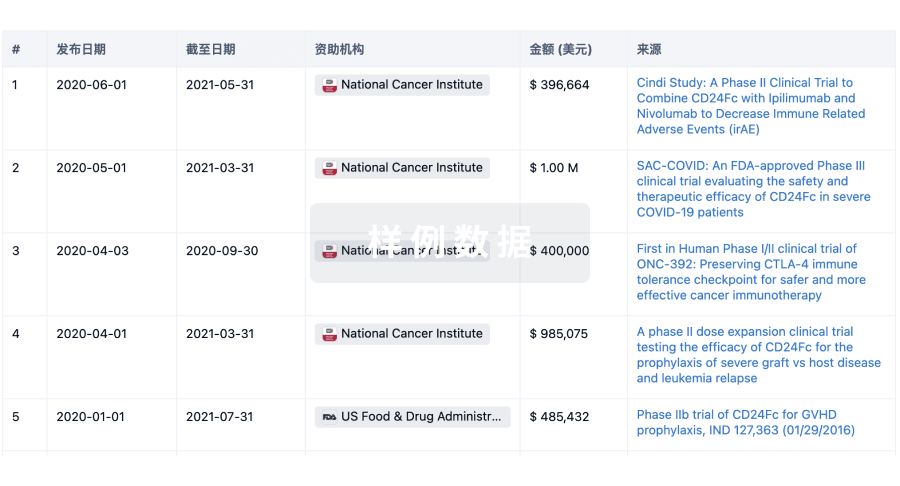
科研基金(NIH)
访问超过 200 万项资助和基金信息,以提升您的研究之旅。
登录
或
投资
深入了解从初创企业到成熟企业的最新公司投资动态。
登录
或
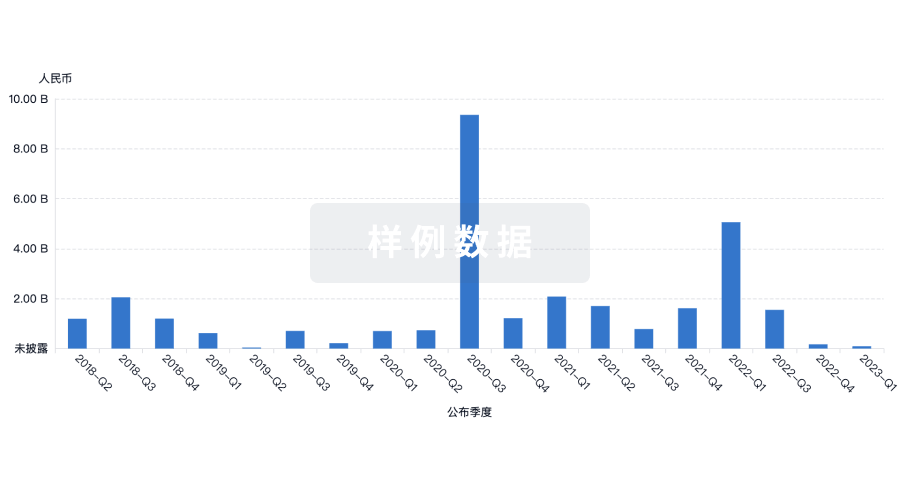
融资
发掘融资趋势以验证和推进您的投资机会。
登录
或
提出任何生物医药研究问题
让每一步生物医药决策都精准制胜
基于十亿级生物数据与全球情报的精准 AI,赋能早期药物发现
立即开始免费试用!
智慧芽新药情报库是智慧芽专为生命科学人士构建的基于AI的创新药情报平台,助您全方位提升您的研发与决策效率。
立即接入生物医药数据包
智慧芽新药库数据也通过智慧芽开放平台,以MCP或API服务形式对外开放。立即使用我们的MCP服务定制您的LLM智能体。
生物序列数据库
生物药研发创新
免费使用
化学结构数据库
小分子化药研发创新
免费使用