预约演示
更新于:2026-09-20
Wuhan University
更新于:2026-09-20
概览
标签
肿瘤
感染
皮肤和肌肉骨骼疾病
小分子化药
蛋白水解靶向嵌合体(PROTAC)
预防性疫苗
疾病领域得分
一眼洞穿机构专注的疾病领域

技术平台
公司药物应用最多的技术
靶点
公司最常开发的靶点
关联
靶点 |
作用机制 |
在研机构 |
原研机构 |
在研适应症 |
非在研适应症 |
最高研发阶段 |
首次获批国家/地区 |
首次获批日期 |

靶点 |
作用机制 |
在研机构 |
原研机构 |
在研适应症 |
非在研适应症 |
最高研发阶段 |
首次获批国家/地区 |
首次获批日期 |
靶点 |
作用机制 |
在研机构 |
原研机构 |
在研适应症 |
非在研适应症 |
最高研发阶段 |
首次获批国家/地区 |
首次获批日期 |
ChiCTR2600129843
The effect of gratitude intervention based on broaden-and-build theory on social isolation in young and middle-aged lymphoma patients during chemotherapy
ChiCTR2600127602
The impact of intervention based on the Thinking Healthy Programme on antenatal depression symptoms and pregnancy outcomes: A randomized controlled trial
ChiCTR2600129587
The Association Between GIS-Based Food Environment and Dental Caries in Adolescents: A Mixed-Methods Study
100 项与 武汉大学 相关的临床结果
登录后查看更多信息
登录后查看更多信息
2027-01-01NEURAL NETWORKS
Injecting reasoning into vision-language models via weight-decomposed merging
Article
作者: Zhao, Qinghong ; Li, Yapeng ; Wei, Yipan ; Wang, Leyan ; Du, Bo ; Zou, Yuchen
Model merging offers a promising training-free paradigm for integrating capabilities across pretrained models. While recent advances have demonstrated that merging large language models (LLMs) into vision-language models (VLMs) can endow them with reasoning abilities, we observe that standard weight merging strategies originally designed for structurally homogeneous models often introduce semantic inconsistencies between the vision and language modules. In many cases, this leads to degraded performance after merging, with visual grounding accuracy dropping by more than 50% in some scenarios. In this paper, we propose a weight-decomposed merging framework that explicitly decouples pretrained parameters into directional and magnitude components, and merges them independently to preserve representational alignment. Our method is simple, training-free, and compatible with heterogeneous model architectures. Through extensive empirical evaluation across three VLMs, four reasoning-capable LLMs, and three multimodal reasoning benchmarks, we show that our approach achieves strong and competitive performance in heterogeneous LLM-to-VLM merging settings. The results indicate that weight-decomposed merging provides a stable training-free pathway for reasoning injection while mitigating severe performance degradation observed in several baseline merging methods. The code is available at https://github.com/YC-Zou/Weight-Decomposed-VLM-Merging.
2026-12-31RENAL FAILURE
Targeting LRH-1 alleviates diabetes-induced lipotoxicity in podocytes: role of PLIN5-mediated lipid droplet turnover
Article
作者: Ding, Guohua ; Wang, Juan ; Hu, Hongtu ; Yang, Qian ; Zhu, Zijing ; Fan, Yanqin ; Guan, Qian ; Ye, Peng ; Hu, Jijia
Diabetic kidney disease (DKD) is characterized by podocyte injury driven by intracellular lipid accumulation. Liver receptor homolog-1 (LRH-1) is a key nuclear receptor regulating lipid metabolism, yet its role in podocyte lipotoxicity remains unclear. This study identifies the LRH-1/perilipin 5 (PLIN5) axis as a critical pathway for maintaining lipid homeostasis in podocytes and a promising pharmacological target for DKD. We demonstrated that hyperglycemia suppressed the LRH-1/PLIN5 axis, leading to lipid droplet accumulation, oxidative stress, and podocyte injury in db/db mice and cultured podocytes. Activation of LRH-1 with agonist 1,2-dilauroyl-sn-glycerol-3-phosphocholine (DLPC) or its overexpression restored mitochondrial lipid utilization, reduced lysosomal lipotoxicity, and protected against renal injury by upregulating PLIN5. Furthermore, virtual screening of a natural product library identified chebulinic acid (CA) as a novel PLIN5-targeting agonist. CA treatment significantly upregulated PLIN5 expression, ameliorated lipid accumulation, and improved renal function in db/db mice. Our findings unveil the therapeutic potential of targeting the LRH-1/PLIN5 axis and present CA as a promising candidate for the treatment of diabetic podocytopathy.
2026-12-31Plant Signaling & Behavior
DHQS
regulates pollen-pistil interaction via the shikimic acid pathway in
Arabidopsis thaliana
Article
作者: Peng, Xiongbo ; Wang, Xiu
The normal production of pollen and proper pollen-pistil interaction are critical for double fertilization in Arabidopsis. Previous studies have demonstrated that DHQS affects female gametophyte development and pollen tube funicular guidance during fertilization. However, whether DHQS influences pollen development and pollen-pistil interaction remains unknown. In this study, we analyzed pollen and sperm cell morphology in dhqs-1/+ mutant. Results showed that DHQS does not affect sperm cell formation but significantly reduces pollen grain size. Pollen germination assays revealed no impairment in dhqs-1 pollen germination. However, semi-in vitro experiments demonstrated that dhqs-1 pollen tubes exhibited delayed growth through stigmas compared to wild-type. Notably, supplementation of shikimic acid in the medium significantly alleviated the growth inhibition of dhqs-1 pollen tubes in wild-type stylar tissue, underscoring the essential role of shikimic acid in mediating pollen-pistil interaction. These findings suggest that DHQS regulates pollen-pistil interaction through the shikimic acid pathway, providing novel insights into the molecular mechanisms underlying fertilization in plants.
2026-09-18
·信达生物
100 项与 武汉大学 相关的药物交易
登录后查看更多信息
100 项与 武汉大学 相关的转化医学
登录后查看更多信息
组织架构
使用我们的机构树数据加速您的研究。
登录
或
管线布局
2026年09月20日管线快照
管线布局中药物为当前组织机构及其子机构作为药物机构进行统计,早期临床1期并入临床1期,临床1/2期并入临床2期,临床2/3期并入临床3期
药物发现
14
40
临床前
其他
45
登录后查看更多信息
当前项目
登录后查看更多信息
药物交易
使用我们的药物交易数据加速您的研究。
登录
或
转化医学
使用我们的转化医学数据加速您的研究。
登录
或
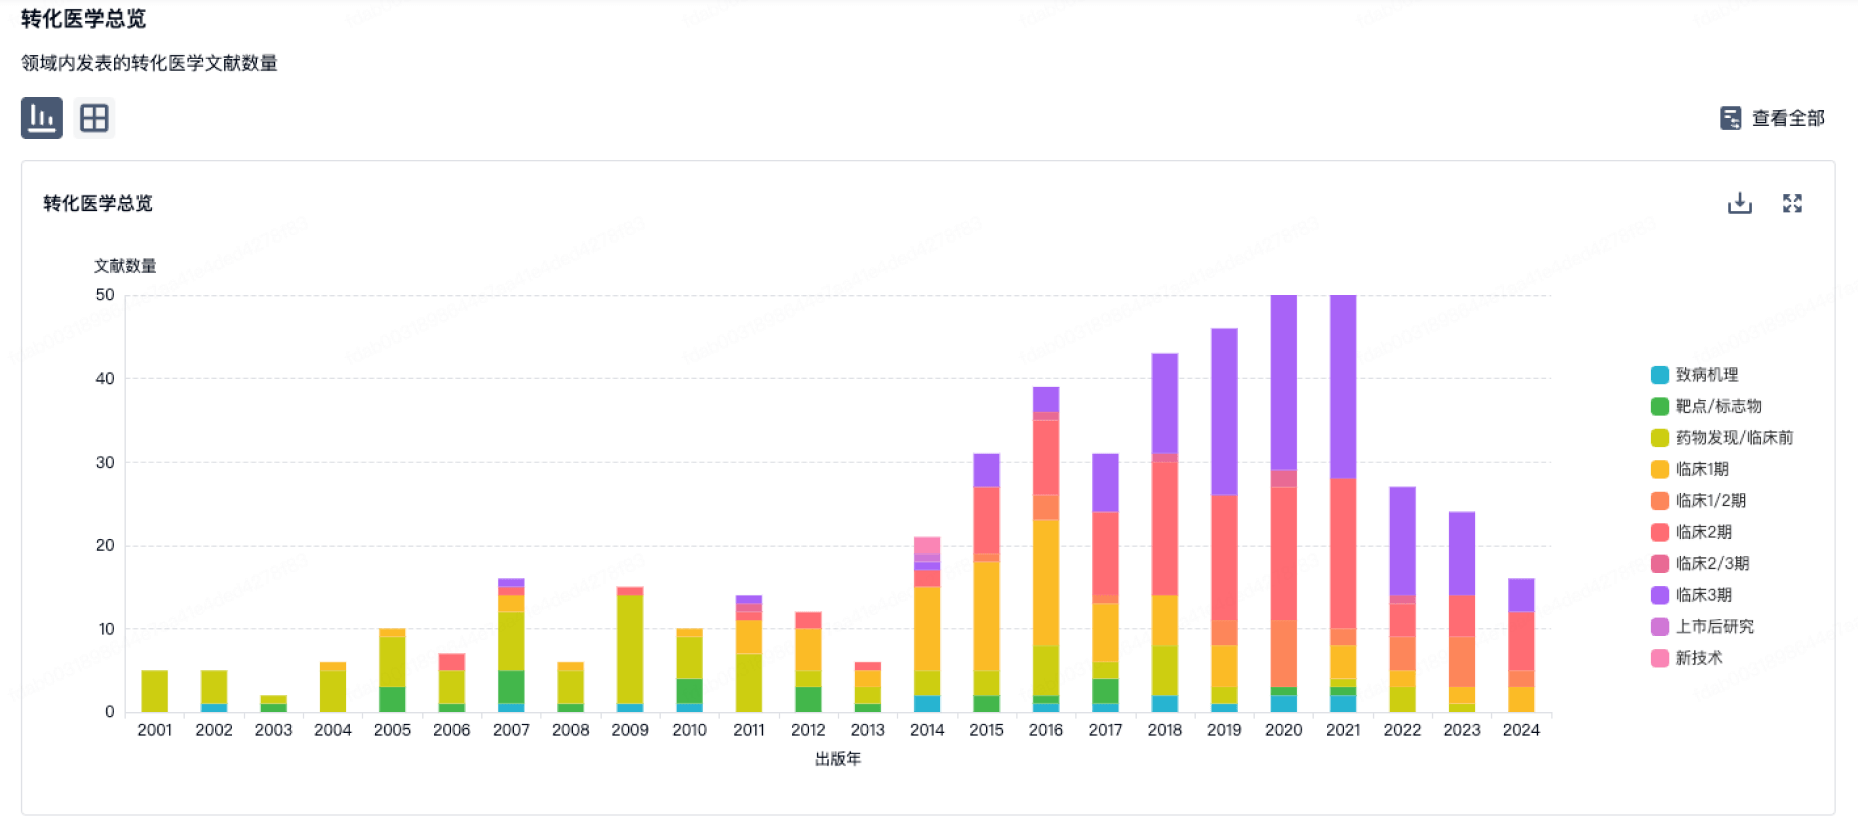
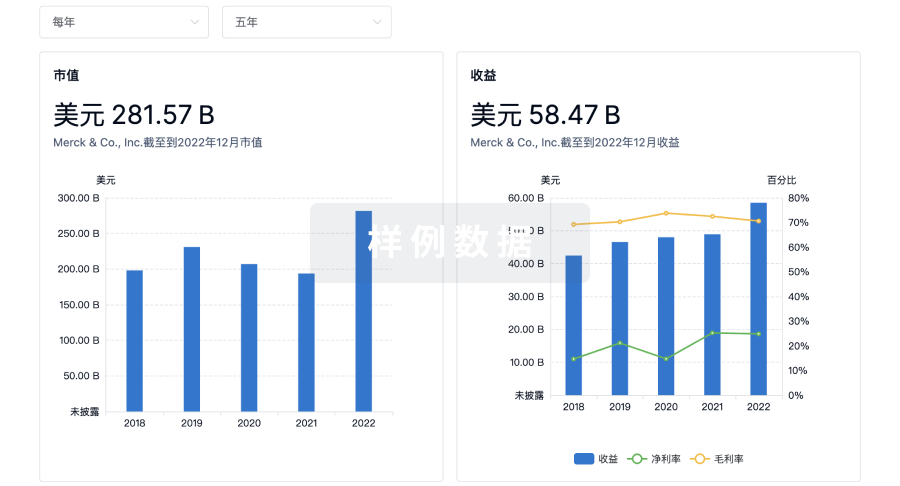
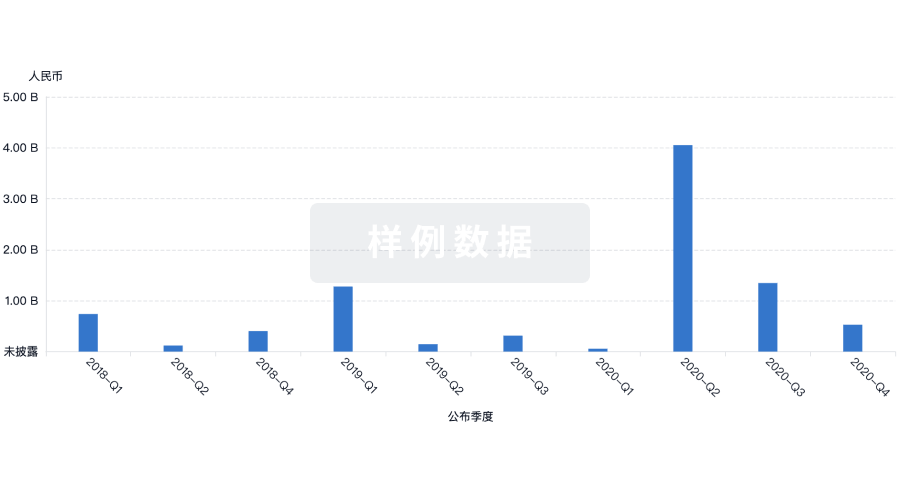
营收
使用 Synapse 探索超过 36 万个组织的财务状况。
登录
或
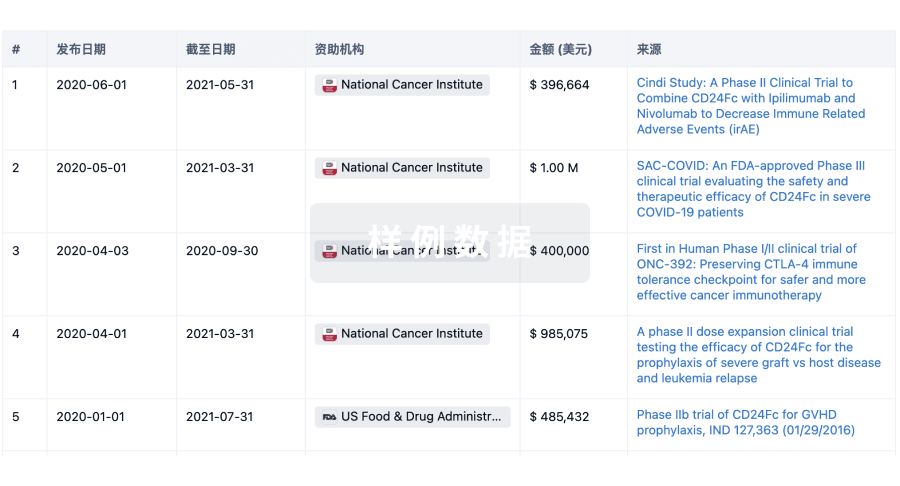
科研基金(NIH)
访问超过 200 万项资助和基金信息,以提升您的研究之旅。
登录
或
投资
深入了解从初创企业到成熟企业的最新公司投资动态。
登录
或
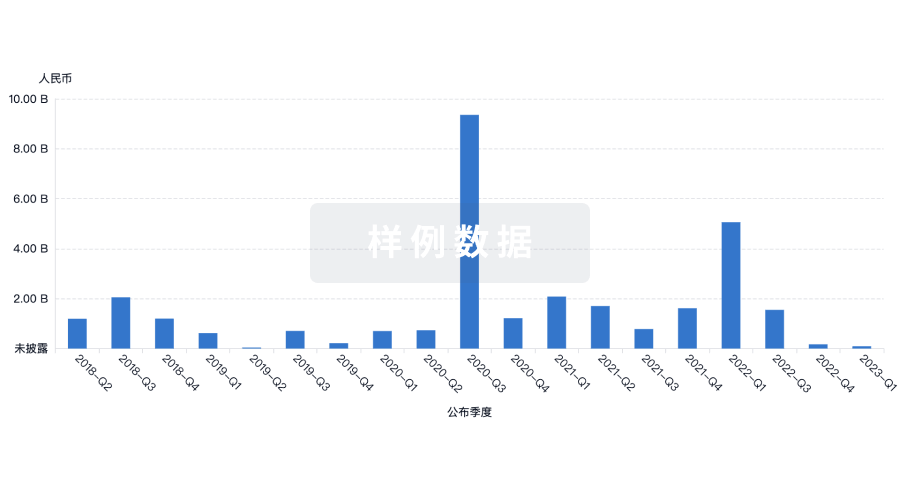
融资
发掘融资趋势以验证和推进您的投资机会。
登录
或
提出任何生物医药研究问题
让每一步生物医药决策都精准制胜
基于十亿级生物数据与全球情报的精准 AI,赋能早期药物发现
立即开始免费试用!
智慧芽新药情报库是智慧芽专为生命科学人士构建的基于AI的创新药情报平台,助您全方位提升您的研发与决策效率。
立即接入生物医药数据包
智慧芽新药库数据也通过智慧芽开放平台,以MCP或API服务形式对外开放。立即使用我们的MCP服务定制您的LLM智能体。
生物序列数据库
生物药研发创新
免费使用
化学结构数据库
小分子化药研发创新
免费使用